Local-First AI: Redacting PII and Mastering Privacy in Modern LLM Pipelines
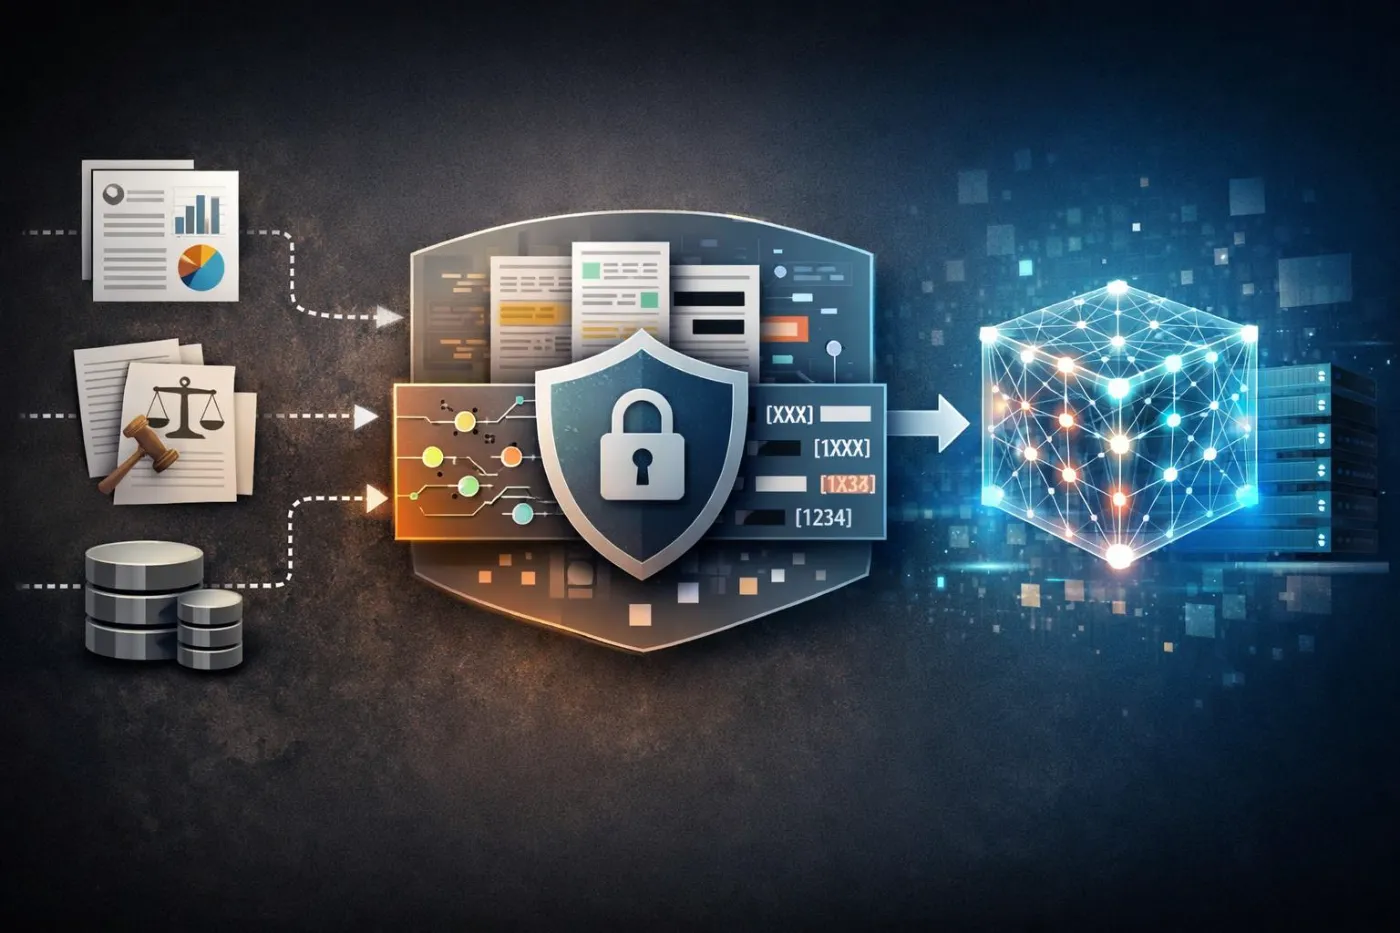
Meta description: Learn how to protect personal data in LLM pipelines with local-first AI, PII detection and redaction, secure retrieval, and practical GDPR and PDPA controls.
Introduction: Privacy needs to be designed into the pipeline
Large language models can help teams search documents, summarize support cases, extract information, and automate workflows. But prompts and retrieved context can also contain names, email addresses, account identifiers, financial details, health information, or confidential business data. Once sensitive information flows through a model provider, logging service, vector database, evaluation platform, or third-party tool, the privacy problem becomes larger than the model call itself.
A safer approach is to design the entire system around data minimization and controlled movement. Local-first AI is one useful pattern: process sensitive information locally or within a controlled environment whenever practical, and send only the minimum necessary data to external services. Pair that architecture with detection, redaction or tokenization, access controls, retention limits, and testing.
Local-first does not automatically mean private, and redaction does not automatically make data anonymous. A local service can still expose data through logs or weak access controls, while supposedly anonymized text may remain identifiable through context. The goal is to reduce exposure and demonstrate that privacy controls work throughout the lifecycle.
This guide is for engineering, security, privacy, and product teams building LLM applications. It explains how to design a privacy-aware pipeline, choose appropriate controls, and prepare for obligations that may arise under the EU General Data Protection Regulation (GDPR), Singapore’s Personal Data Protection Act (PDPA), and other applicable privacy laws.
This article is general technical information, not legal advice. Requirements depend on jurisdiction, processing purpose, data type, organizational role, and the specific facts of a deployment.
1. What local-first AI means in practice
Local-first AI prioritizes processing and storing data close to the organization or user, with external transmission limited to what is necessary. “Local” can mean different things depending on the system:
- On-device: Processing happens on a user’s computer or mobile device.
- Self-hosted: Models and supporting services run on infrastructure managed by the organization.
- Private cloud or controlled tenant: Processing runs in a restricted environment with defined access, retention, and network controls.
- Hybrid: Sensitive preprocessing and policy enforcement happen locally, while a hosted model receives a minimized or transformed request.
The right option depends on latency, model capability, hardware, operating cost, threat model, and data sensitivity. A local model may reduce data transfers but require more operational work and may not match the performance of a hosted model for every task. A hosted service may be appropriate when its contractual and technical controls meet the use case’s requirements.
The architecture decision should be based on a documented risk assessment—not the assumption that one deployment style is always safest.
2. Map every place personal data can travel
Teams often focus on the prompt sent to the model and overlook the rest of the pipeline. Privacy risk can arise at ingestion, retrieval, tracing, analytics, support, and evaluation stages.
A typical LLM pipeline may include:
- Input sources: Web forms, support tickets, call transcripts, emails, documents, and databases.
- Preprocessing: Parsing, OCR, language detection, normalization, and PII detection.
- Retrieval: Search indexes, embeddings, vector databases, and document stores.
- Model inference: Local or hosted language models and embedding services.
- Tool calls: CRM, ticketing, payment, identity, or internal APIs.
- Output handling: Generated answers, summaries, extracted fields, and actions.
- Observability: Logs, traces, prompt histories, error reports, and usage analytics.
- Evaluation and improvement: Test datasets, annotation tools, feedback records, and model assessments.
Create a data-flow diagram that identifies the data owner, purpose, storage location, recipients, retention period, and access permissions for each component. Include subprocessors and backups where relevant. If the team cannot explain where prompts and traces are stored, it cannot reliably explain the privacy posture of the system.
3. Build a PII detection and redaction layer
Personally identifiable information (PII) is information that identifies or can help identify a person. Depending on context and applicable law, this can include direct identifiers such as names and email addresses, as well as combinations of attributes that identify someone indirectly.
A practical detection layer often combines several methods:
- Pattern matching: Regular expressions for formats such as email addresses, phone numbers, and known identifier patterns.
- Named-entity recognition: Models that detect names, locations, organizations, and other entities in text.
- Contextual rules: Domain-specific checks for policy numbers, customer IDs, account references, and other structured values.
- Allowlists and denylists: Rules for approved fields and prohibited data classes, maintained with care to avoid false confidence.
- Human review or escalation: Appropriate for ambiguous, high-impact, or poorly supported cases.
No single detector is sufficient for every language, document format, or domain. Pattern matching can miss unusual formats; entity recognition can confuse ordinary words with names; and a detector may not understand that several individually harmless details identify someone when combined.
Redaction, masking, and tokenization are different
- Redaction removes or replaces sensitive values, for example
[EMAIL_REDACTED]. - Masking hides part of a value, such as displaying only the last few digits of an account identifier.
- Tokenization or pseudonymization replaces a value with a stable token, while a separate protected mapping may allow re-linking.
- Anonymization aims to make identification no longer reasonably possible under the relevant standard and context; it is substantially harder than replacing names.
Use the method that fits the task. A general summarization request may not need a customer’s name or full account number. A workflow that must update a specific record may need a stable token that the trusted application can resolve after the model response. Keep any re-identification mapping outside the model context, encrypted, access-controlled, and auditable.
Example: Minimize before sending
Instead of sending a raw support message such as:
“I’m Priya Shah, my email is priya@example.com, and my policy number is AB123456. Why was my claim delayed?”
A minimized model input could be:
“A customer asks why a claim is delayed. The policy status is ‘documents pending’; the next required document is a repair estimate.”
If the model only needs to explain the next step, the customer’s identity and direct identifiers add no value. The trusted application can attach the verified claim status and deliver the response through the authorized channel.
This example is illustrative. Redaction rules should be tailored to the actual task, and any quoted user content should be handled according to the organization’s policies.
4. A reference architecture for a privacy-aware LLM pipeline
A useful design puts privacy enforcement before the model and checks outputs before they reach users or downstream systems.
The diagram is conceptual. A real deployment should define which components are inside the trusted boundary, which vendors receive data, and how each boundary is enforced technically.
5. Privacy in retrieval-augmented generation (RAG)
RAG systems can expose sensitive information even when the prompt itself contains no direct identifiers. The retrieval layer may return documents that the current user is not authorized to see, or an embedding service may receive text before redaction is applied.
Use these controls:
- Filter before embedding where appropriate. Do not send raw personal data to an external embedding service without assessing the purpose, data flow, and safeguards.
- Enforce permissions at retrieval time. Apply document- and tenant-level authorization before content enters the model context.
- Keep metadata useful but minimal. Index only the attributes needed for retrieval and access decisions.
- Manage deletion across the full lifecycle. When source records are deleted or access changes, define how indexes, caches, derived chunks, and backups are updated.
- Test for leakage. Ask whether one user can retrieve another user’s records, infer sensitive facts, or extract information through repeated queries.
- Protect embeddings and indexes. Embeddings are not automatically anonymous; treat them according to the sensitivity of the source and the realistic risks of inference or linkage.
- Show provenance where useful. Let users or reviewers trace important claims to authorized source documents.
Avoid treating a vector database as a harmless technical cache. It can become a secondary store of personal or confidential information and should be included in data inventories, access reviews, retention schedules, and incident plans.
6. Secure prompts, outputs, logs, and tools
Redacting the initial prompt is only one control. A model can reproduce sensitive details from retrieved content, infer attributes, or place personal information in its output. Tool calls can also send data to other services.
Inspect outputs before disclosure
Apply output checks where appropriate, especially before sending responses externally or writing to a system of record. Check for accidental identifiers, secrets, unsupported claims, and data that the requesting user is not authorized to receive. Output filters should complement access control, not replace it.
Treat logs as sensitive data stores
Debug logs often collect raw prompts, completions, tool arguments, stack traces, and retrieved passages. This can create a shadow database of personal data. Prefer structured metadata, redacted samples, request identifiers, and error categories over unrestricted prompt capture. Restrict access to detailed traces and set retention periods.
Constrain tool access
An agent should not be able to query arbitrary customer records simply because a model can form a query. Use narrow APIs, least-privilege credentials, trusted identity context, argument validation, and independent authorization checks. For consequential actions, require confirmation or human approval and verify the result before reporting success.
Protect secrets and configuration
Never place API keys, credentials, or private signing material in prompts, retrieval indexes, or source-controlled configuration. Use a secrets manager, rotate credentials, and separate development, staging, and production environments.
7. GDPR and PDPA: Translate legal principles into engineering controls
Privacy law is not a single checklist that applies identically to every organization. The GDPR applies within its material and territorial scope; Singapore’s PDPA has its own scope, definitions, obligations, and exceptions. Other national and sectoral laws may also apply. Organizations should determine their role, purpose, data categories, locations, and relevant obligations with qualified privacy or legal advisers.
The following mapping is an engineering aid, not a legal determination.
| Privacy concern | Practical engineering response | Governance question |
|---|---|---|
| Lawful and transparent processing | Record the purpose, identify data flows, provide appropriate notices, and avoid unnecessary collection | What is the applicable basis or authority for this processing, and what must people be told? |
| Purpose limitation and minimization | Send only the fields needed for the task; separate optional context from required inputs | Is each data element necessary for the stated purpose? |
| Accuracy | Validate extracted data against authoritative sources and provide correction routes | How can incorrect personal data be corrected before it affects a decision? |
| Retention limitation | Set deletion rules for prompts, traces, indexes, caches, and backups | How long does each component need to retain this data? |
| Security and confidentiality | Encrypt data, restrict access, manage secrets, and monitor suspicious activity | Are safeguards proportionate to the likely harm and data sensitivity? |
| Individual rights | Build processes to locate relevant records and respond to applicable requests | Can the organization find data across prompts, logs, vendors, and derived stores? |
| Processor and vendor management | Review contracts, subprocessors, access, retention, incident handling, and international transfers | Who receives the data, under what terms, and where is it processed? |
| Accountability and impact assessment | Maintain records, conduct appropriate risk assessments, and test controls | What evidence demonstrates that risks have been assessed and mitigated? |
GDPR considerations
Depending on the circumstances, GDPR-related work may include identifying an appropriate lawful basis, meeting transparency duties, respecting purpose limitation and data minimization, supporting applicable data subject rights, managing processors, securing personal data, and assessing international transfers. A data protection impact assessment may be required for processing likely to result in a high risk to individuals. Special-category data and automated decision-making may trigger additional requirements.
Do not assume that removing direct identifiers removes GDPR obligations. Pseudonymized data generally remains personal data when it can be linked back to a person using additional information or otherwise relates to an identifiable individual.
Singapore PDPA considerations
Where Singapore’s PDPA applies, review relevant obligations concerning notification, consent where applicable, purpose limitation, accuracy where relevant, protection, retention limitation, access and correction, data breach notification, and transfers of personal data outside Singapore. The details depend on the facts, statutory provisions, and applicable exceptions.
Do not assume that a local model by itself establishes compliance. Purpose, access, retention, security, and the organization’s responsibilities still need to be addressed.
Document the decisions
Keep a record of the use case, data categories, processing locations, vendor assessments, chosen safeguards, retention rules, testing results, and accountable owners. This helps engineering teams maintain controls and gives privacy, security, and compliance teams evidence to review.
8. Choosing between local, hosted, and hybrid models
| Approach | Potential advantages | Trade-offs to assess |
|---|---|---|
| On-device or self-hosted model | Greater control over data movement and infrastructure | Hardware, maintenance, patching, model quality, monitoring, and capacity planning |
| Private or dedicated hosted environment | Managed infrastructure with configurable access and contractual controls | Provider dependency, service configuration, data location, retention, and subprocessors |
| General hosted API with minimized data | Lower operational burden and access to capable models | Whether the provider’s terms, data handling, regional processing, and controls fit the use case |
| Hybrid local-first pipeline | Sensitive preprocessing can remain controlled while external inference handles selected tasks | More components, integration complexity, and the need to prevent data from leaking through side channels |
Ask vendors specific questions: Are prompts or outputs used for training? What retention applies to requests, abuse monitoring, and support? Which subprocessors are involved? Where is processing performed? What deletion and access controls are available? How are incidents communicated? Which contractual terms govern the data?
Answers should be verified against current documentation and contracts. Product labels such as “private,” “enterprise,” or “secure” are not substitutes for a data-flow and risk assessment.
9. Test whether redaction really works
A privacy control that has not been evaluated may create false confidence. Build a test suite that reflects the languages, formats, and data types in your environment.
Include:
- Common and unusual email, phone, address, account, and policy-number formats.
- Names embedded in free text, signatures, tables, scans, and OCR output.
- Multilingual text, transliteration, and mixed-language conversations.
- Indirect identifiers and combinations of attributes that could identify a person.
- False positives where a harmless word resembles an identifier.
- Sensitive data returned by retrieval, tools, and model-generated outputs.
- Attempts to bypass redaction using spacing, punctuation, encoding, or prompt injection.
- Tenant-boundary and authorization tests for retrieval and tool access.
Track precision (how often flagged items really need treatment) and recall (how much of the sensitive information is detected), but do not stop at a single aggregate score. A missed high-risk identifier can matter more than many low-impact false positives. Set thresholds by data type and task, and include manual review for high-risk workflows.
Test the full path from ingestion to logs and downstream tools. A pipeline that redacts model inputs but stores raw content in traces is not privacy-safe.
10. A 30-day implementation plan
Week 1: Discover and classify
- Map the LLM applications, models, vendors, tools, indexes, logs, and evaluation systems in use.
- Identify personal, sensitive, confidential, and regulated data categories.
- Document purpose, access, processing location, recipients, and retention for each component.
- Choose one use case with a clear purpose and manageable risk.
Deliverable: A data-flow map and initial risk register.
Week 2: Minimize and protect
- Remove fields that the model does not need.
- Add PII detection and redaction or tokenization before external processing where appropriate.
- Enforce authorization before retrieval and tool execution.
- Configure secrets management, encryption, access logging, and retention limits.
Deliverable: A controlled pipeline with documented data boundaries.
Week 3: Evaluate and review
- Build a representative PII test set with approved handling and access.
- Measure detection precision and recall by data type.
- Test prompt injection, output leakage, logging, and cross-tenant access.
- Review vendors, contracts, data locations, and applicable legal obligations with privacy and security teams.
Deliverable: Evaluation results and an agreed remediation list.
Week 4: Pilot and operate
- Pilot with a limited user group or low-risk task.
- Monitor redaction failures, access denials, quality, latency, and cost.
- Confirm incident response, deletion, and individual-request processes where applicable.
- Assign owners and define the conditions required before expanding scope.
Deliverable: A pilot review with measured controls and a go/no-go decision.
11. Common mistakes to avoid
Assuming local means safe. Local deployments still need access controls, patching, logging discipline, encryption, and incident response.
Redacting only names and emails. Account references, rare combinations of attributes, free-text narratives, and metadata can also identify people.
Sending raw text to an embedding service first. Embedding generation is part of the data flow and needs the same review as model inference.
Keeping raw prompts forever for debugging. Unrestricted logs can become a long-lived source of exposure. Use minimization, access control, and defined retention.
Calling pseudonymization anonymization. If a person can be re-identified through a protected mapping or other available information, the data may still be personal data.
Relying on a vendor checkbox. Confirm actual retention, training use, processing locations, subprocessors, deletion, and contractual commitments.
Using a filter instead of an authorization system. Output scanning can catch some leaks, but it cannot replace permissions enforced before data is retrieved or actions are executed.
Failing to retest changes. A new model, parser, prompt, document source, or logging configuration can change privacy risk. Treat material changes as a reason to rerun tests.
Conclusion: Make privacy a property of the architecture
Privacy-aware LLM engineering is not just a redaction function inserted before a model call. It is a set of coordinated controls across data collection, preprocessing, retrieval, inference, tools, outputs, logs, evaluation, retention, and incident response.
Local-first design can reduce unnecessary data movement. PII detection and minimization can reduce what the model sees. Retrieval-time authorization, protected mappings, secure tool interfaces, and disciplined logging help prevent sensitive information from escaping through other paths. Testing and documentation turn these choices into controls that teams can verify and maintain.
For GDPR, Singapore PDPA, and other applicable regimes, the engineering implementation should follow a documented understanding of the organization’s role, purpose, data flows, and legal obligations. No single architecture guarantees compliance, and no detector catches every possible identifier.
At Raxon Labs, the practical starting point is to map one LLM workflow, remove data it does not need, enforce access before retrieval, minimize external transfers, and test the entire pipeline—including logs and downstream tools. Build privacy into the system from the start, then expand only when the safeguards work in practice.
Frequently asked questions
What is local-first AI?
Local-first AI prioritizes processing and storing information on a device or within an organization-controlled environment, limiting external transfers to what is necessary. It can involve on-device, self-hosted, private-cloud, or hybrid designs.
Does PII redaction guarantee GDPR or PDPA compliance?
No. Redaction is one technical safeguard. Organizations must also assess applicable legal obligations, purpose, access, security, retention, vendor relationships, transparency, individual rights, and other requirements relevant to their processing.
Are embeddings anonymous?
Not automatically. Embeddings can retain information about their source and may create risks of inference or linkage. Treat them according to the sensitivity of the source data and the realistic threat model.
Should every company run its own LLM locally?
No. Self-hosting can provide more infrastructure control but introduces operational and security responsibilities. A hosted or hybrid model may be appropriate when the data flow, provider terms, controls, and risk assessment support it.
Where should PII redaction happen in an LLM pipeline?
As early as practical, before data reaches components that do not need the identifiers. Also apply access controls before retrieval, inspect outputs where appropriate, and minimize sensitive information in logs and evaluation datasets.
Further reading
- European Union: General Data Protection Regulation (GDPR)
- European Data Protection Board
- Singapore Personal Data Protection Commission (PDPC)
- Singapore Personal Data Protection Act 2012 — Singapore Statutes Online
- NIST Privacy Framework
- OWASP Top 10 for Large Language Model Applications
Review current official guidance and obtain qualified legal advice before relying on a specific compliance interpretation.